Same brief, five plans
A 158-word brief for a daily spending app. Brief only, then epics, stories, features and a sprint plan (414 to 2,614 words).
Planning vs vibe coding / Codex builds
More detailed plans scored a little higher on a screenshot checklist. The grading could not show which plan made the better app.
01 / Setup and grading
A 158-word brief for a daily spending app. Brief only, then epics, stories, features and a sprint plan (414 to 2,614 words).
gpt-6-astra at high reasoning, the same scaffold and synthetic bank data, 60 minutes per build, no shared results.
25 hidden checks per app: pass 1, partial 0.5, fail 0. Checks it could not see were excluded, not passed.
625 check slots in total; 391 graded. Excluded means no score assigned, not a pass or a missing feature.
The judge saw anonymized screenshots only: no source code, no clicking. Excluded checks shrink the denominator, so 80% on 10 graded checks is not 80% of a product. All 250 browser-task records have no success verdict, and longer plans added implementation detail as well as structure.
02 / Results
| Approach | Added instructions | Mean build | Mean judged score | Checks graded | Screenshot UI |
|---|---|---|---|---|---|
| Brief only | The shared short brief | 34.6 min | 90.1% | 76 / 12560.8% coverage | 2.8 / 5 |
| Brief + epics | + high-level user outcomes | 34.7 min | 92.2% | 81 / 12564.8% coverage | 2.8 / 5 |
| Epics + stories | + stories with done-when checks | 34.1 min | 94.7% | 75 / 12560.0% coverage | 3.2 / 5 |
| Epics + features + stories | + features grouping the stories | 39.8 min | 94.5% | 79 / 12563.2% coverage | 3.0 / 5 |
| Sprint plan | + estimates and four sprints | 38.7 min | 95.9% | 80 / 12564.0% coverage | 2.8 / 5 |
Five builds per row, in planning order, not a leaderboard. The score is the mean of five build scores. UI ratings are screenshot ratings, not hands-on usability scores.
234 of 625 check slots were excluded, leaving 391 graded slots. A higher score is not proof that planning caused it or that the app handles money better.
03 / Conclusion
Observed
All 25 builds finished and booted. A long backlog was not needed to get a running prototype.
Observed
Sprint had the highest mean checklist score, stories the best UI rating. Large ungraded shares limit what that means.
Not established
Planning time, debugging and repair effort were not measured, so total effort saved is unknown.
04 / Hands-on follow-up
| Task | Verified | Not established |
|---|---|---|
| Trace a payment to its bank source | 5 / 5 verified | 0 unverified |
| Keep a budget and note after reload and restart | 5 / 5 verified | 0 unverified |
| Repeat daily sync without adding duplicates | 3 / 5 verified | 2 unverified |
13 / 15 task checks verified; 2 unverified, not failed. None of the five sampled apps had statement upload or removal; that is not established for all 25 builds.
05 / Next time
Advice prompted by the gaps, not a winning workflow proven by the experiment.
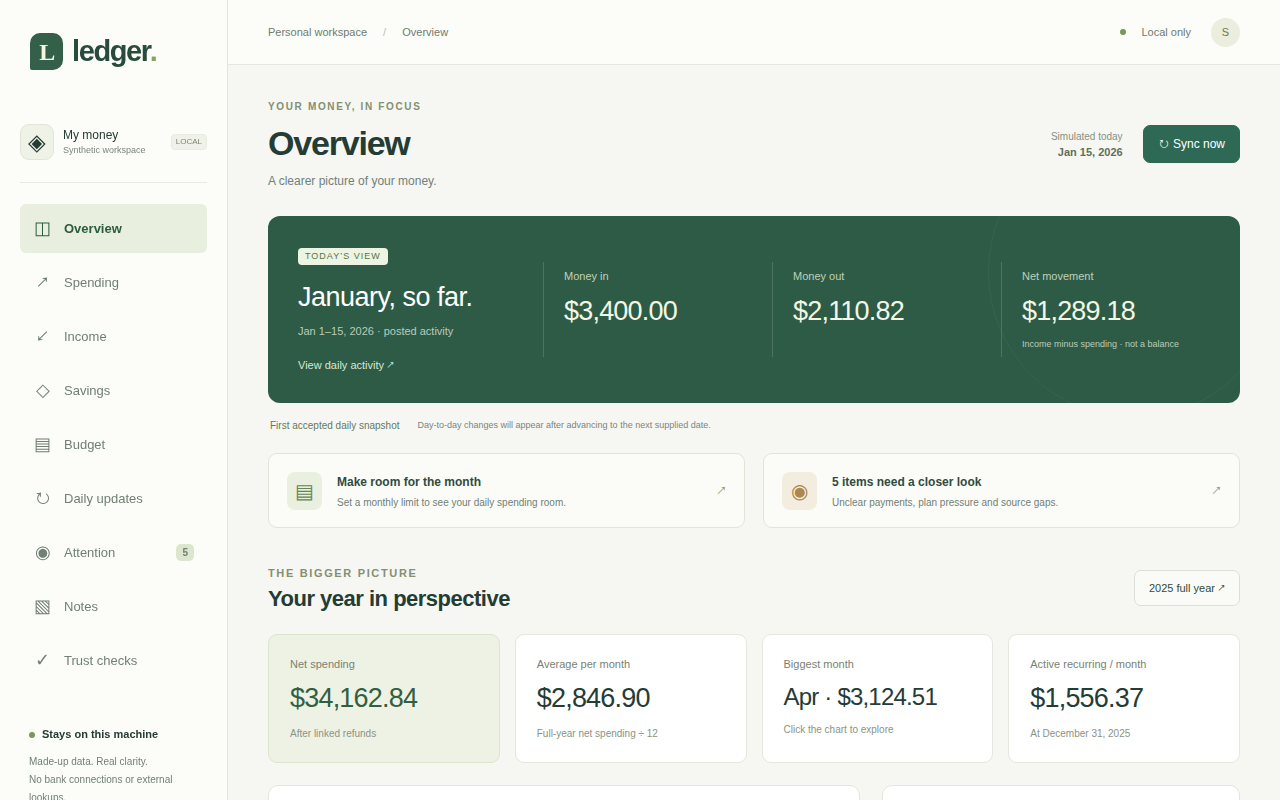
06 / See the apps
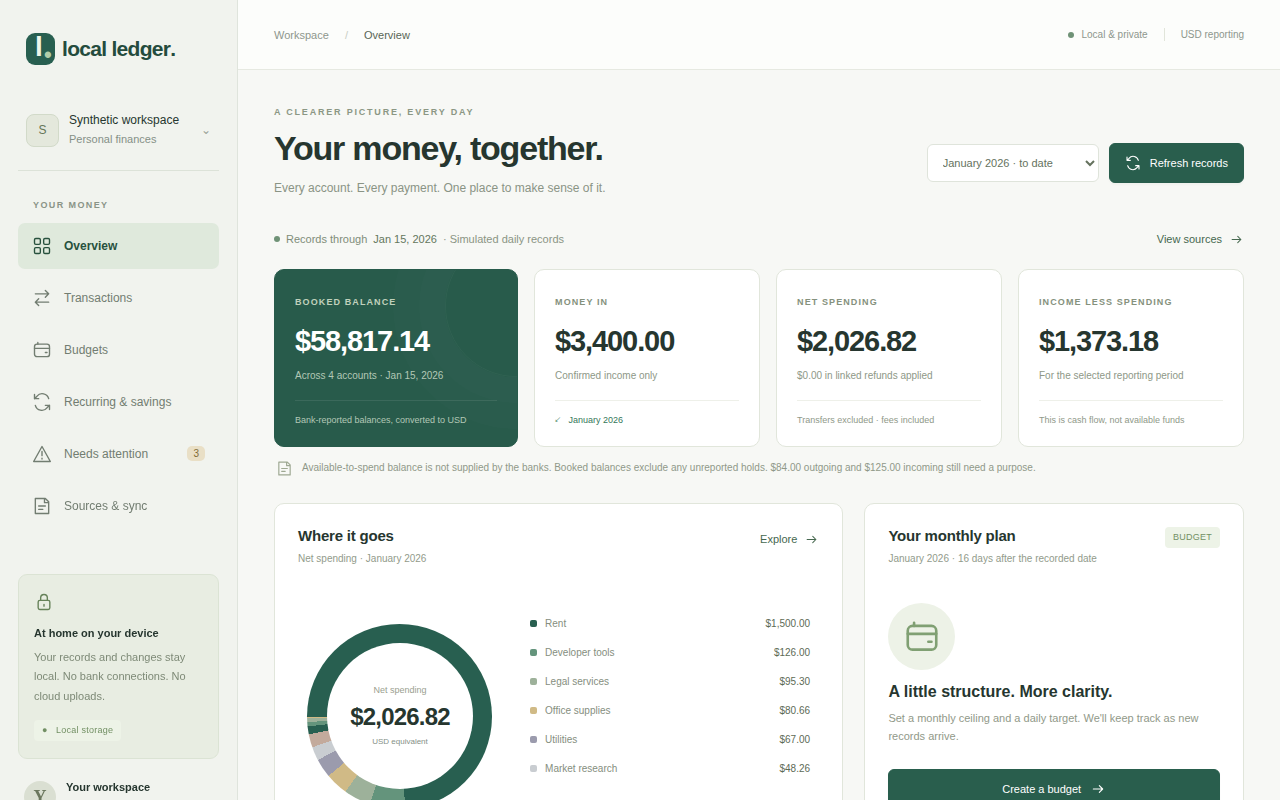
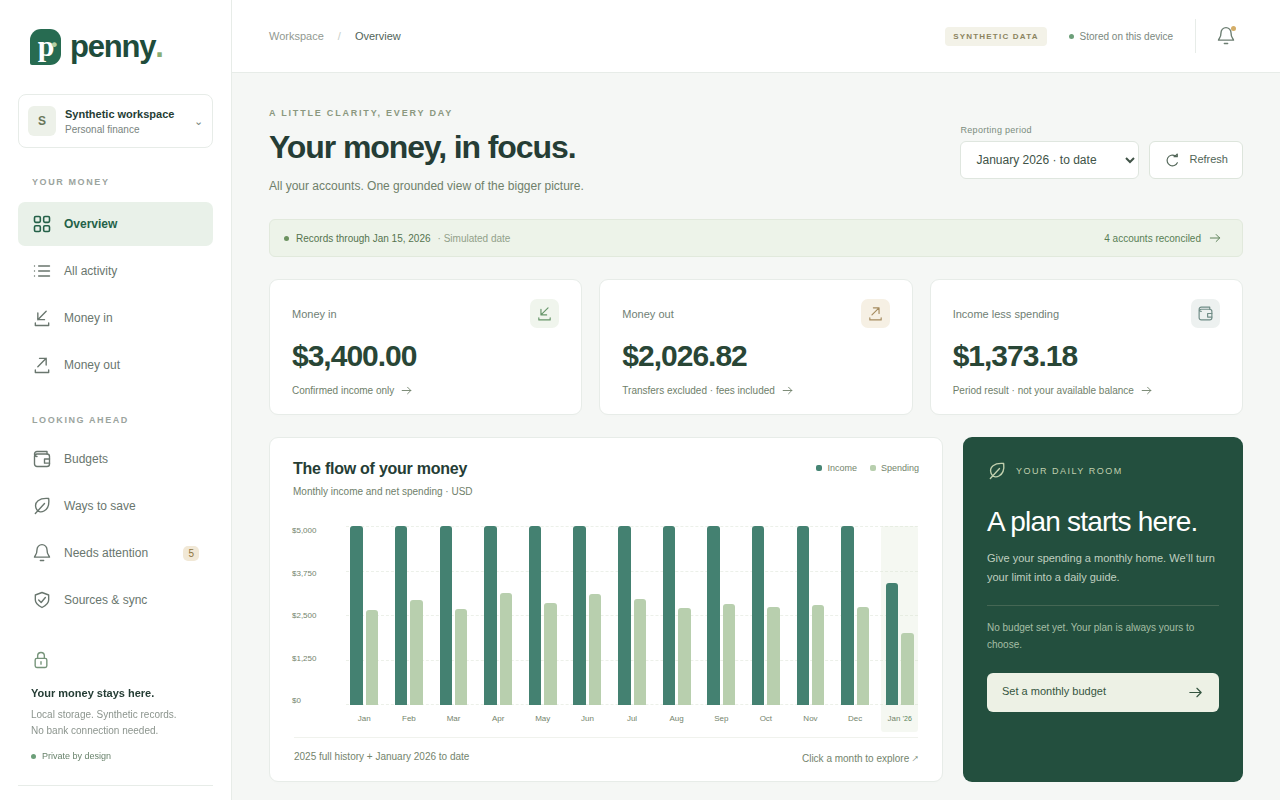
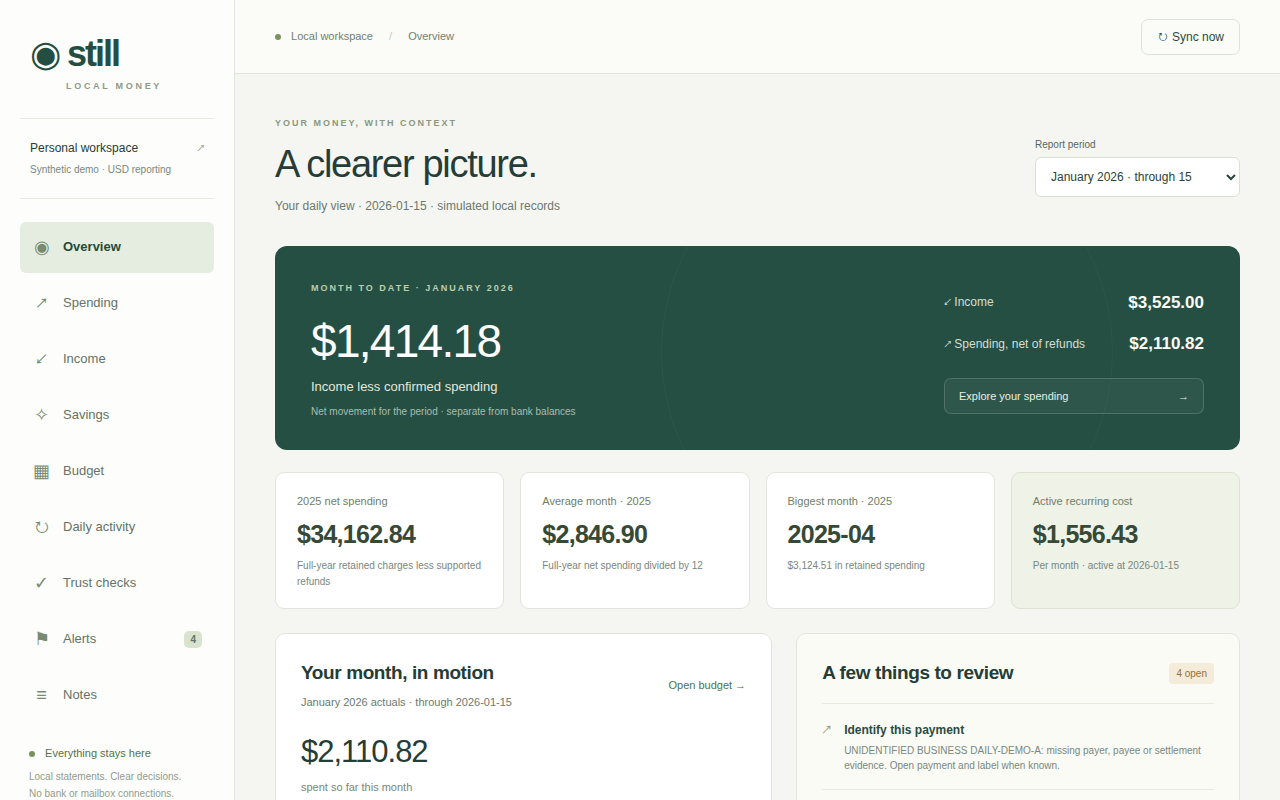
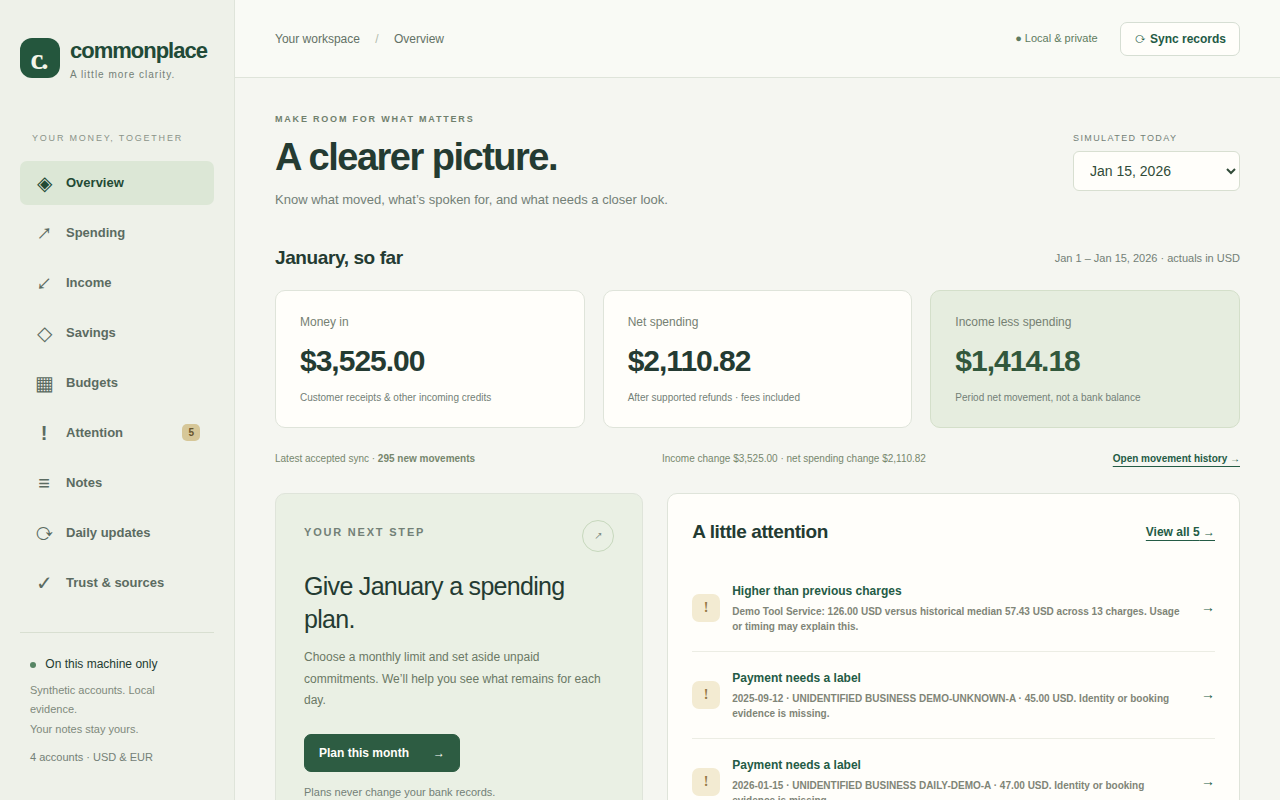
Each plan's best-scoring build, as built in the experiment. All bank data is invented.